📊 Full opportunity report: Qwen3.8-Max: A New Reference Point For Coding And Cowork? on IdeaNavigator AI — validation score, market gap, and execution plan.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
IdeaNavigator AI identifies a Hacker News item titled “Qwen3.8-Max: A New Bar for Coding and Cowork” as a signal for operations leads monitoring AI tools. The material provides no model documentation, benchmark results, release details or independent evaluation, so it does not establish that Qwen3.8-Max sets a new coding standard.
IdeaNavigator AI has flagged a Hacker News item titled “Qwen3.8-Max: A New Bar for Coding and Cowork” as a development that operations leads rolling out AI across small teams may want to monitor. The material assigns the item an 88/100 signal score, but gives no model release information, technical details or benchmark evidence to confirm the title’s claim that it sets a new standard.
The item is presented as part of an AI operations signal monitor concept: a service that tracks feeds such as Hacker News, filters developments for a particular role and turns relevant items into short briefs. The intended reader is an operations lead introducing AI tools to a small team, who may need to decide whether a new capability warrants testing, policy review or no immediate action.
IdeaNavigator AI describes the Hacker News score as a reason to examine the item, not as a measure of model quality. The material contains no link to an evaluation, no named benchmark, no comparison with other models and no reported tests of coding or collaborative (“cowork”) tasks. It also does not specify who developed the model, when it became available, or what the “cowork” label means.
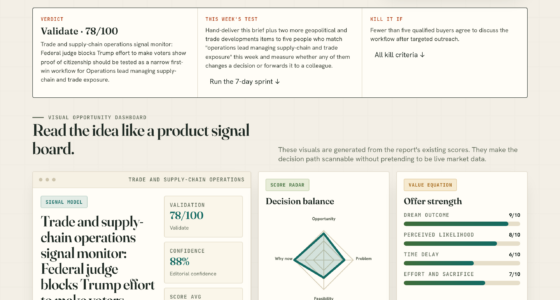
The proposed monitor would translate each selected development into a what changed, why it matters and what to do brief. IdeaNavigator AI suggests testing the service by hand-delivering this item and two other AI capability or policy developments to five people matching the target role, then checking whether the recipients change a decision or forward a brief to a colleague. That is a validation proposal, not evidence that the service has been built, that users have tried it or that it has paying customers.
AI Operations Signal · October 2026
Qwen3.8-Max: A New Reference Point for Coding and Cowork?
A Hacker News headline has been flagged for operations leads. The available material offers no release details, technical documentation, benchmarks, or independent evaluation to verify its performance claim.
Model release
Unclear
No date or access details
Benchmarks
None cited
No methods or results
Monitor status
Proposed
MVP and test plan described
Suggested pilot
5 people
Early validation idea
What the signal does—and does not—say
Separate the headline from the evidence
The item is presented as an example of an AI operations monitor surfacing a development. It is not a product announcement or a firsthand account of model performance.
What is reported
A surfaced headline
IdeaNavigator AI flags a Hacker News item titled “Qwen3.8-Max: A New Bar for Coding and Cowork” as potentially relevant to small-team operations leads.
What is missing
Evidence of capability
No developer, model card, release date, task definition, benchmark, comparison baseline, test conditions, or independent evaluation is provided.
Practical stance
Verify before acting
Treat the claim as a prompt to investigate. No adoption decision or internal product change is supported by the available description.
The proposed service
From model headline to team brief
Track
Monitor feeds such as Hacker News, news sites, and policy updates.
Filter
Select developments for a defined role, such as an operations lead.
Brief
Summarize what changed, why it matters, and what to do next.
Validate
Measure whether readers change a decision or pass the brief along.
Why operations teams may care
Workflow impact needs proof
A better coding model or stronger collaboration features could matter to a team. Those are possible implications, not established outcomes for Qwen3.8-Max.
Potential area
Code drafting and review
If measured improvements exist, a team might assess whether AI changes development speed, review quality, or the checks people need to perform.
Potential area
Delegation and teamwork
“Cowork” is undefined in the source material. Readers cannot determine whether it refers to software collaboration, workplace assistance, or another task.
Monitor value
Less feed sorting
Role-specific briefs could save time, but their usefulness depends on accurate selection and enough evidence for readers to make decisions.
Evidence checklist
What would verify the signal?
Look for details that let a team reproduce the comparison and judge whether the result applies to its own work.
To assess the model claim
- A dated announcement and technical documentation from the developer.
- Defined coding and collaboration tasks, with benchmark names and test conditions.
- Scores, baseline models, and a clear evaluation method.
- Independent results or reproducible tests, alongside developer claims.
To assess the monitor idea
- Deliver three briefs to five people who match the target role.
- Track whether recipients change a decision or forward a brief.
- Report whether interviews or trials actually took place and when.
- Separate observed responses from future plans; a small pilot is an early signal.
Reader guide
Key questions
The available information leaves the central model claim and the monitor’s current status unresolved.
Has Qwen3.8-Max outperformed other coding models?
No performance evidence is provided: there are no benchmark results, comparison baselines, or independent evaluations.
What does 88/100 mean?
It is attributed to the Hacker News signal. The scoring method is not explained, and it is not a measure of model capability.
Is the monitor available now?
The description outlines a proposed MVP and a validation plan. It does not confirm a launch, completed trial, customers, or revenue.
Why Operations Teams Are Watching
For teams adopting AI, the practical question is not whether a headline sounds ambitious; it is whether a tool changes a workflow enough to justify a test, staff training or a change in internal guidance. A genuinely improved coding model could matter to teams that use AI to draft or review code, while stronger collaborative features could affect how staff delegate and check work. Those are possible implications, not established outcomes for Qwen3.8-Max.
The monitor concept addresses a separate operational problem: developments are spread across news sites, forums and policy updates, making it difficult for a small team to distinguish actionable changes from general discussion. A role-specific brief could reduce the time spent sorting through feeds, but its value depends on the quality of its selection and whether it gives readers enough evidence to make decisions. The 88/100 score alone does not show that the item is accurate, important or relevant to a particular organization.
The suggested test focuses on observable behavior rather than general interest: did a recipient alter a decision or share the brief? That could help assess whether the service is useful to its intended audience. However, a five-person trial would be an early signal, not broad proof of demand, reliability or commercial viability.
Products Worth Considering

Samsung 32 Odyssey G5 QHD Gaming Monitor

LG UltraGear 34G600A-B 34-Inch Curved WQHD Gaming Monitor

LG 27GS60QC-B Ultragear 27-inch Curved Gaming Monitor (QHD, 180Hz, 1ms, 1000R)
As an affiliate, we earn on qualifying purchases.
From Model Headline to Team Brief
The available description combines two separate ideas: a headline about Qwen3.8-Max and a proposed information service for AI operations. It frames the model item as an example of the kind of signal the service might surface. It does not provide a product announcement or a firsthand account of model performance.
The proposed service would monitor Hacker News and similar feeds, apply a filter based on the needs of an operations lead, and summarize relevant developments into a short decision-oriented brief. The stated business model is a subscription for people who need early, role-filtered information about AI capabilities and policy. No subscription price, launch date, product specifications or existing customer figures are given.
IdeaNavigator AI’s proposed first test is to share three briefs with five people who match the intended role and track whether the information affects a decision or is passed on. That plan positions the concept as an early-stage validation exercise; it does not establish that the monitoring service is operating or that the Qwen3.8-Max item has been independently assessed.
Model Claims Still Need Evidence
The material does not establish what Qwen3.8-Max is, who made it, whether it has been released, or what tasks it supports. No model card, technical documentation, access details or date are provided. The word “cowork” is not defined, so readers cannot tell whether it refers to software collaboration, workplace assistance or another capability.
There are also no test methods or results behind the phrase “a new bar” for coding. Without benchmark names, scores, baselines, test conditions or independent evaluations, the headline should be treated as a claim rather than a verified comparison. The 88/100 figure is attributed to the item’s Hacker News signal, but the scoring method, underlying data and meaning of the number are not explained.
The status of the monitoring concept is also unclear. The description outlines an MVP and a user-validation plan, but does not say whether any interviews or trials have taken place. It provides no evidence of user decisions, referrals, subscription interest or revenue.
What Would Verify the Signal
The next useful step for readers assessing the model claim would be to locate a dated announcement or technical documentation and look for transparent coding and collaboration evaluations. Any comparison should identify the tasks tested, the baseline models, the scoring method and whether results came from the developer or an independent evaluator. Until those details are available, the headline does not support a conclusion about model performance.
For the monitoring idea, IdeaNavigator AI proposes delivering this brief alongside two other AI capability or policy items to five operations leads and measuring whether they change a decision or forward the information. The description does not provide a date for that test or report that it has begun. A later update would need to distinguish completed interviews and measured responses from proposed validation steps.
For small teams, the practical takeaway is to treat the item as a prompt to verify, not a recommendation to adopt a tool. If documentation or reproducible evaluations emerge, teams can judge whether a controlled trial fits their workflows, privacy requirements and review practices. No adoption decision or product change is confirmed here.
Source: IdeaNavigator AI
Key Questions
Has Qwen3.8-Max been shown to outperform other coding models?
No performance evidence is provided in the available material. It gives no benchmark results, comparison baseline or independent evaluation.
What does the 88/100 signal score mean?
IdeaNavigator AI says Hacker News surfaced the item with an 88/100 signal. It does not explain the scoring method or say that the number measures model capability.
Is the AI operations monitor already available?
The description presents a proposed minimum viable product and validation plan. It does not confirm that the service has launched or that the planned user test has been completed.
How is IdeaNavigator AI proposing to test the concept?
It proposes sending this brief and two other AI capability or policy updates to five operations leads, then tracking whether they change a decision or forward an item to a colleague.
Source: IdeaNavigator AI