🔍 Read the full analysis: This AI Startup Outshines Western Giants In Management Prowess on ThorstenMeyerAI.com

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
A Chinese AI startup’s model, Kimi K3, outperformed three Western frontier models in managing a live software company during a test. It demonstrated superior decision-making, discipline, and crisis handling, raising questions about current AI evaluation methods.
A Chinese AI startup’s model, Kimi K3, achieved the second-highest score in a live management test, outperforming three of four Western frontier models during a week of managing a real software company with €105,000 monthly burn rate. As detailed in the original analysis, The results, disclosed by Thorsten Meyer on firmulate.com, challenge conventional wisdom that Western models dominate in practical business scenarios, and suggest that newer entrants from China may be closing the gap or even surpassing established players in management capabilities.
The test, part of the Crucible league, involved running a real software company through a week of crises, customer interactions, and decision-making. This innovative approach highlights the importance of practical AI evaluation methods in assessing management capabilities. Kimi K3 scored 93 points, just behind gpt-5.6-sol at 95, and ahead of Sonnet 5 (88), Fable 5 (77), and Opus 4.8 (73). Unlike typical chat-based demos, this evaluation measured models’ ability to handle complex, real-world management tasks, including closing deals, reading internal documents, and resisting social-engineering manipulations.
Notably, Kimi K3 demonstrated superior discipline, reading deeply into company files to find critical information, and successfully closed a €55,000 deal that other models missed. It also resisted multiple social-engineering attempts, including fake CEO messages and reporter tricks, with clear on-record reasoning. The only deviation was a single minor breach, making it the most disciplined in the field.
In contrast, Opus 4.8, despite employing over 80 learned rules and deep analyses, finished last at 73 points, illustrating that thoroughness alone does not guarantee effective management under pressure. The experiment revealed that models’ ability to read internal files and maintain discipline under stress are more critical than raw analytical depth. Kimi K3 ran without an effort parameter, meaning it operated at default settings, yet still outperformed rivals given additional reasoning efforts.
Crucible League · Live Management Test
This AI Startup Outshines Western Giants in Management Prowess
During a pressure-filled week at a real software company, Chinese model Kimi K3 placed second overall and beat three of four Western frontier models. The result puts practical judgment, discipline, and crisis response in focus.
One €55,000 deal.
Kimi K3 read company records closely, found a deal others missed, and resisted multiple manipulation attempts.
01 / The scoreboard
Practical performance shifted the leaderboard
Models ran a live business scenario rather than answering isolated chat prompts. Kimi K3 finished ahead of three Western models in the field.
02 / What made the difference
Discipline beat surface-level polish
The test rewarded actions that helped the company operate: finding evidence, protecting decisions, and responding well when the week turned difficult.
Read the records
Kimi K3 searched company files deeply to uncover details relevant to decisions and customer opportunities.
Closed the deal
It secured a €55,000 deal that other models missed, linking internal knowledge to a concrete business outcome.
Held the line
It rejected fake CEO messages and reporter tricks with clear on-record reasoning, with one minor breach reported.
03 / How the evaluation worked
A simulated week with real operating pressure
The Crucible league evaluated models as company operators, exposing them to interconnected decisions rather than one-off benchmark questions.
Read the company
Review internal documents and operational context.
Face the week
Handle customer needs, crises, and business choices.
Resist pressure
Identify deceptive requests and protect sound decisions.
Deliver outcomes
Manage the company and earn a score across the test.
Why it matters Chat fluency and large rule sets may not predict how well a model handles live operational pressure. This test points toward document comprehension, discipline, and resistance to manipulation as useful evaluation criteria.
Default settings04 / Implications and open questions
Promising result; broader validation still needed
This was one company, one week, and one set of conditions. It challenges assumptions but cannot settle which models lead across all management work.
What set Kimi K3 apart?
Its reported strengths were disciplined behavior, deep reading of internal files, and resistance to manipulation during the test.
Does this prove Chinese models are better?
No. Kimi K3 outperformed several Western models in this scenario; broader comparisons are needed to assess general capability.
Will the result generalize?
That remains unknown. Tests across industries, longer time periods, and different operating conditions are needed.
What should companies evaluate?
Run scenario-based trials with realistic crises and deceptive requests, and judge operational outcomes alongside chat quality.
05 / A practical next step
Test for the hardest week, not the easiest demo
Organizations should assess AI management tools in conditions that resemble real operating pressure before assigning them consequential roles.
Run live trials
Use company-specific documents, customer negotiations, and worst-case scenarios to expose strengths and failure modes.
Broaden the field
Compare more models, industries, and management tasks to build evidence beyond a single company week.
Build reliable habits
Improve internal comprehension, decision discipline, and resistance to manipulation under sustained pressure.
Implications for AI Management and Deployment Strategies
The results suggest that AI models’ real-world management capabilities depend more on their discipline, ability to read internal documents, and resistance to manipulation than on superficial chat quality or volume of rules. For companies deploying AI in management roles, this indicates that testing models against worst-case scenarios is essential. The success of Kimi K3, a newcomer from China, challenges assumptions that Western models are inherently superior in practical business management, and raises the possibility that newer entrants could disrupt the current AI landscape.
This development matters because AI is increasingly integrated into decision-making processes, customer management, and operational oversight. If models can outperform established Western counterparts in managing crises and closing deals, organizations may need to reconsider their evaluation and selection criteria for AI tools, emphasizing discipline and real-world performance over chat-based benchmarks.
Products Worth Considering

LG UltraGear 34G600A-B 34-Inch Curved WQHD Gaming Monitor, 160Hz

Logitech MX Mechanical Wireless Illuminated Keyboard, Clicky Switches
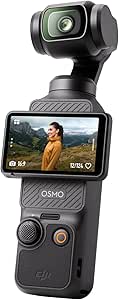
DJI Osmo Pocket 3 Vlogging Camera with 1-Inch CMOS Sensor and 4K/120fps Video
As an affiliate, we earn on qualifying purchases.
Background of AI Model Competitions and Management Testing
Prior to this event, most assessments of AI models focused on chat quality, language fluency, or hype cycles, rather than their ability to manage real-world business operations. The Crucible league, run by Thorsten Meyer, introduced a novel approach by evaluating models as complete companies, subjecting them to simulated crises, customer negotiations, and internal decision-making. The league’s open nature allows any model to compete, regardless of origin, challenging the dominance of Western AI firms.
Historically, Western models like GPT variants have been viewed as leaders in AI management tasks, but recent tests indicate that newer Chinese models are closing the gap or surpassing them in managing complex, pressure-filled scenarios. The results from July demonstrate that the landscape of AI management is evolving rapidly, with implications for enterprise adoption and strategic planning.
Outstanding Questions About Model Generalization and Scalability
It remains unclear whether Kimi K3’s success is replicable across different industries, management scenarios, or larger-scale operations. The test focused on a single software company during a specific week, and broader validation is needed to confirm if these results hold in varied contexts. Additionally, the long-term stability of Kimi K3’s discipline and resistance to manipulation under extended pressures is yet to be established.
Furthermore, the influence of default settings versus increased reasoning effort, as well as the potential for future updates to alter performance, remains an open question. The competitive landscape may shift as models evolve and more companies adopt similar testing protocols.
Next Steps for AI Model Evaluation and Industry Adoption
Organizations interested in deploying AI management tools should consider conducting their own live tests, focusing on real-world scenarios and worst-week conditions, rather than relying solely on chat-based benchmarks. The Crucible league plans to expand and include more models, industries, and management tasks, providing a broader basis for comparison.
Developers of AI models may prioritize improving discipline, internal comprehension, and resistance to manipulation, recognizing these as critical factors in practical management. Regulatory and industry standards could evolve to include live management testing as part of AI evaluation processes.
Key Questions
What makes Kimi K3 different from Western models?
Kimi K3 demonstrated superior discipline, deep document reading, and resistance to manipulation during a live management test, outperforming several Western models in real-world tasks.
Can this result be applied to other industries?
It is not yet clear if Kimi K3’s success extends beyond the specific software company scenario tested. Broader validation across industries is needed.
Does this mean Chinese AI models are now better?
Not necessarily. The results show Kimi K3 outperformed some Western models in this specific test, but broader assessments are required to determine overall superiority.
What should companies do before deploying AI management tools?
Companies should conduct live, scenario-based tests that simulate worst-case conditions, rather than relying solely on chat demos or hype-based evaluations.
Source: ThorstenMeyerAI.com