🔍 Read the full analysis: 7 Takeaways From Profiling TorchNeuron At The System Level On AWS Trainium on ThorstenMeyerAI.com

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
Hugging Face has published Part 1 of a TorchNeuron profiling tutorial, demonstrating how to trace RMSNorm inference across PyTorch, the Neuron runtime and AWS Trainium hardware. It compares three implementations as a profiling exercise, but the source material does not provide timing results or identify a performance winner.
Hugging Face has published Part 1 of a TorchNeuron profiling tutorial showing how to trace RMSNorm inference across PyTorch, the Neuron runtime and AWS Trainium, as detailed in the original analysis. The walkthrough compares three implementations of the operation, but the supplied source describes the profiling method rather than reporting measurements or a fastest implementation.
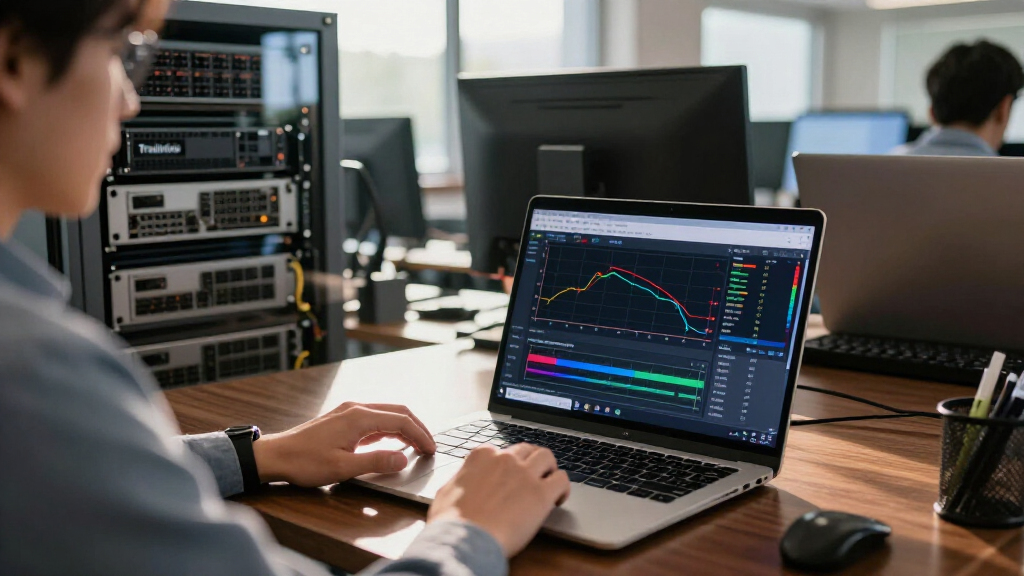
The tutorial uses TorchNeuron, an open-source PyTorch backend for Trainium, with PyTorch’s profiler and Neuron profiling tools. It explains how to collect framework, runtime and device traces so users can follow an operation from framework dispatch through runtime scheduling to execution on a NeuronCore. It also describes using Neuron Explorer to inspect system traces, device timelines and per-engine activity. Learn more about running Hugging Face models on Trainium with TorchNeuron.
The example profiles three versions of RMSNorm: a sequence of ordinary PyTorch operations, the built-in torch.rms_norm() operation lowered to a fused Neuron kernel, and the naive implementation compiled with torch.compile. The tutorial says the examples share inputs, profiler configuration and schedule. Its sample input is a 4-by-512 bfloat16 tensor on a Neuron device.
For the capture, the walkthrough configures NeuronConfig to select data streams, NeuronCores and an output directory, then passes it to torch.profiler.profile as an experimental configuration. It also uses NeuronProfiler to export framework and Neuron system traces. The example enables CPU and PrivateUse1 activities and calls torch.neuron.synchronize() during the profiling loop, which the tutorial says is needed to make device time appear in the profiler output.
Tracing Delays Across Trainium
The guide addresses a practical problem for machine-learning teams: a slow inference call does not, by itself, show where time is spent. A profiler table can report device time alongside Self CPU time, while system traces can show how work moves through framework dispatch, runtime scheduling and accelerator execution. Those views can help practitioners investigate whether delays arise in software overhead, runtime handling or device work.
That distinction matters when deciding whether to use a fused operator, compile a sequence of operations or investigate another part of a model. But the tutorial provides a measurement workflow, not evidence of a performance advantage. Without its timing table and trace findings, readers cannot use this source to conclude that any of the three RMSNorm versions is faster, or that the example predicts results for their own workloads.
Products Worth Considering

Jackery Explorer 300 Portable Power Station with 40W Solar Panel, 292Wh

Apple iPad 11-inch (A16), 128GB, Wi-Fi, Silver

Jackery Explorer 2000 v2 Portable Power Station with Two 200W Solar Panels
As an affiliate, we earn on qualifying purchases.
Three RMSNorm Paths Compared
TorchNeuron connects PyTorch workloads to AWS Trainium. According to the tutorial, it supports standard PyTorch workflows including eager execution and torch.compile, and can work with the Neuron Kernel Interface for custom operators. It registers through PyTorch’s PrivateUse1 extension point, which lets accelerator backends integrate without a dedicated dispatch key such as CUDA’s.
The example breaks RMSNorm into familiar operations: square the input, compute the mean of the squares, add an epsilon, apply a reciprocal square root, and scale by the input and a weight. The profiler schedule waits for two steps, warms up for one and records one active step across four calls. The tutorial says this is intended to keep initial setup outside the recorded iteration. It points readers to the TorchNeuron examples directory for reproduction and describes NEFF as the compiled executable and NTFF as its hardware instruction trace.
“How to follow one operation through Neuron Explorer, from framework dispatch through runtime scheduling to hardware execution on a NeuronCore.”
— Hugging Face TorchNeuron tutorial
No Timings or Winner Reported
The supplied source ends during the first profiling walkthrough. It does not include the resulting key_averages() table, measurements, Neuron Explorer findings or a comparison of CPU and device time among the three versions. No performance winner is established, and the tutorial does not show whether findings from this small input would generalize to other shapes, batch sizes or full models.
The source also gives no publication date and no schedule for a second installment. It is therefore unclear when further results or additional parts of the series may be available.
Inspect Traces and Repeat Tests
Within the tutorial’s workflow, readers next inspect the exported profiler table and trace, then repeat the capture for the built-in and compiled RMSNorm implementations. They can use the linked example scripts to reproduce the profiles and Neuron Explorer to review runtime and device activity. The supplied source does not say when Hugging Face will publish another installment or whether it will include comparative results.
Key Questions
What did Hugging Face publish?
It published Part 1 of a TorchNeuron profiling tutorial showing how to trace RMSNorm inference on AWS Trainium across PyTorch, the Neuron runtime and the device.
Which RMSNorm implementations does the guide compare?
The tutorial profiles a naive sequence of PyTorch operations, the built-in torch.rms_norm() lowered to a fused Neuron kernel, and the naive version compiled with torch.compile.
Does the source say which implementation is fastest?
No. The supplied material describes how to capture and inspect traces but does not include timing results or identify a fastest implementation.
Why does the tutorial synchronize the Neuron device?
The walkthrough calls torch.neuron.synchronize() in the profiling loop so device work finishes before the profiler advances. It says that without synchronization, the Neuron time column may be empty.
When will the next part appear?
The supplied source identifies the tutorial as Part 1 but gives no publication schedule or details about a subsequent installment.
Primary source: Hugging Face · via ThorstenMeyerAI.com